Ground truthBWM + spatial
ONE-STEP WORLD MODELING RESEARCH · 2026
Beckmann World Models
Direct Terminal-Map Learning for
One-Step Action-Conditioned Prediction
Video comparisons
Selected final-checkpoint samples · local baselines at 5 epochs
Prediction quality
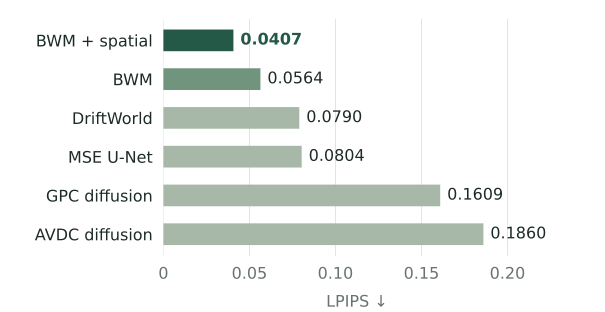
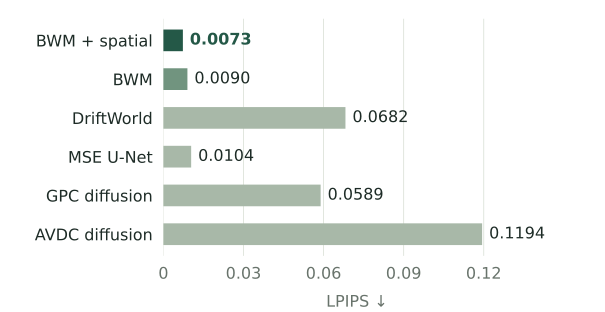
Local baselines: 5 epochs. BWM: staged training; unequal cumulative compute. Bold = best within each table.
MSE: RGB [−1, 1]. Timing: A800 · batch 1 · FP32 · TF32 off.
Released checkpoints
64 frames · reference only| Dataset | Model | MSE ↓ | Moving MSE ↓ | LPIPS ↓ | Calls / chunk | Scope |
|---|
Policy evaluation & planning
| Model | Policy evaluation | GPC-RANK planning | |||
|---|---|---|---|---|---|
| Pearson r ↑ | 95% CI | IoU MAE ↓ | Score ↑ | Δ vs. DriftWorld [95% CI] | |
Policy: 7 policies × 300 paired trials. Planning: 50 fixed seeds. CI: evaluation bootstrap. AVDC: unavailable.
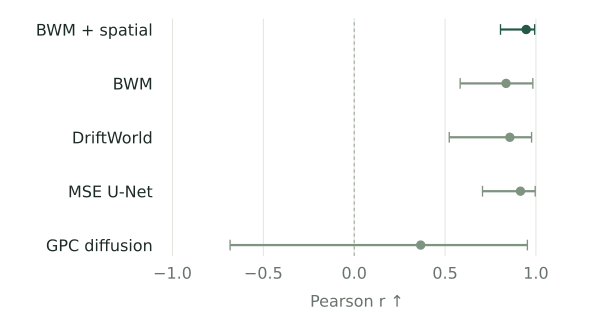
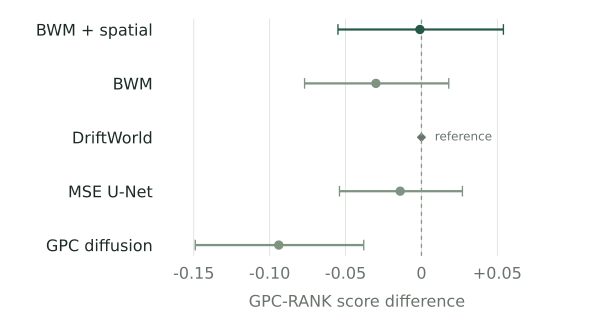
Action conditioning
True actionsSwapped actions
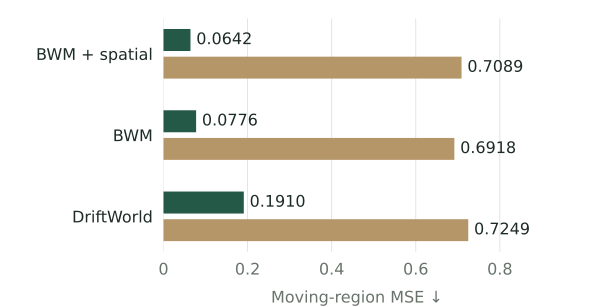
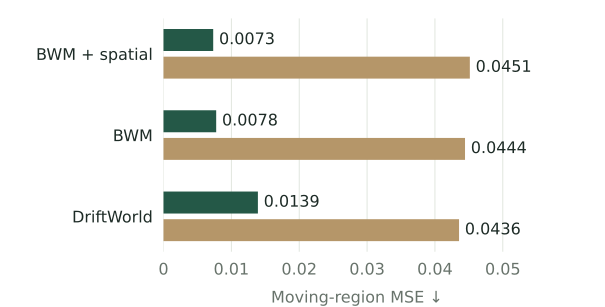
64 validation windows · one chunk · real history. Action sensitivity, not a counterfactual-accuracy test.